What is keypoint annotation?
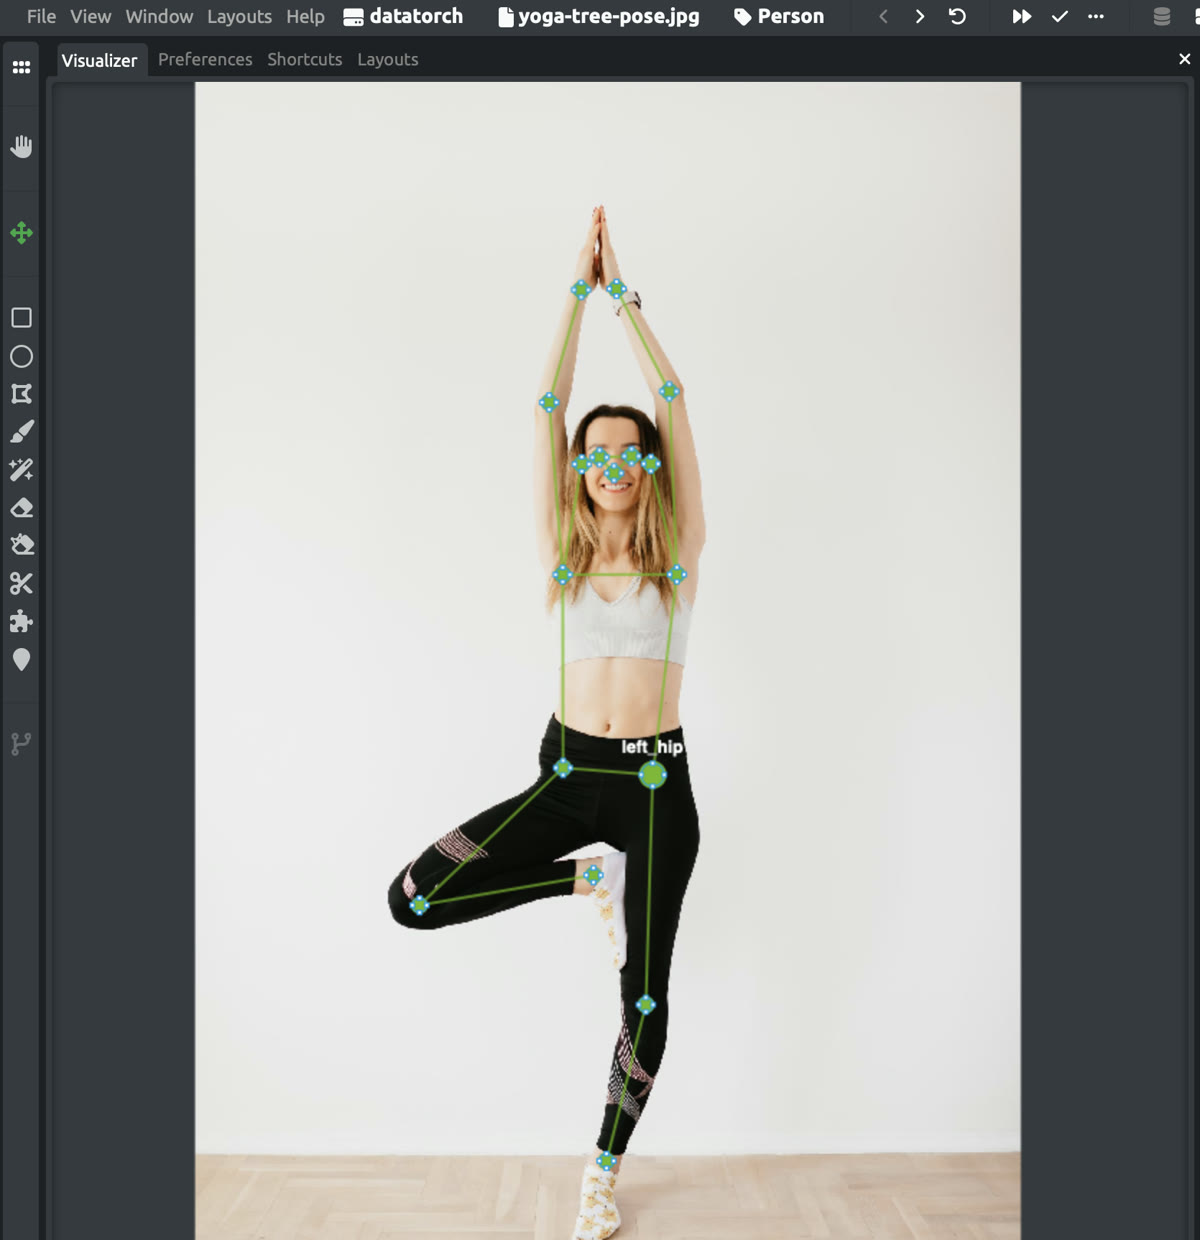
Keypoint annotation is the labeling of specific points of interest on an object in an image, each as a single (x, y) coordinate with a name: a shoulder, a wrist, the corner of an eye, the tip of an instrument. Connected into a skeleton, the points describe the pose or shape of the object, which is what pose estimation and landmark detection models learn to predict.
Annotation is the labeling step, pose estimation is the model task trained on those labels. The same technique covers human pose, facial landmarks, hand tracking, animal pose, sports and clinical motion analysis, and tool tips in robotics or surgery. It is also the annotation type where silent, systematic errors are easiest to make, so this guide covers both the definitions and the workflow that keeps a dataset clean. To place keypoints yourself, there is a step-by-step tutorial for the free browser tool, and there are public keypoint datasets to study before you write a schema.
Keypoints, boxes and masks answer different questions
Bounding box
Where is it, roughly how big?
A rectangle around the whole object. Enough for detection and counting, says nothing about what the object is doing.
Segmentation mask
Exactly which pixels?
The precise outline or pixel set. Captures shape and area, still no notion of the parts inside the object or how they are arranged.
Keypoints
Where are its parts, how is it posed?
Named points with no area, joined by a skeleton. The only one of the three that describes structure: a raised arm, a tilted head, a bent knee.
Four steps, in order
01
Define the schema first
Fix the keypoint names, their order, and the skeleton pairs before anyone places a point. Every downstream consumer (training code, metrics, other annotators) depends on the order being identical across the whole dataset. Changing the schema mid-dataset means re-touching every finished image.
02
Place points, not regions
Each keypoint is a single (x, y) coordinate on a semantic landmark: a joint center, an eye, a tool tip. Aim for the anatomical point, not the visual center of a blob: a wrist is the joint, not the middle of the hand. Consistency across annotators matters more than sub-pixel precision.
03
Mark occlusion explicitly
An occluded landmark still has a location: a hip under a coat exists and is worth estimating. Formats carry a visibility flag per point (COCO: 0 not labeled, 1 labeled but hidden, 2 visible) so models can learn from occluded points without being penalized on them.
04
Review before export
Keypoint errors are systematic, not random: left/right flips, skipped occlusions, and order mistakes repeat across an annotator’s whole batch. A second-pass review of a sample per annotator catches the pattern early, far cheaper than discovering it in model metrics.
The four classic mistakes
Keypoint errors rarely look wrong on screen. They surface weeks later as models that confuse left and right, or metrics that plateau for no visible reason.
Left/right flips
“Left” means the subject’s left: the viewer’s right in a front-facing image, and the viewer’s left when the subject faces away. The single most common keypoint labeling error, and it silently poisons symmetry-aware models.
Occluded ≠ missing
Not-labeled (the point does not exist in the image or was skipped) and labeled-but-hidden are different signals. Collapsing them wastes the occlusion information most pose models can exploit.
Inconsistent order
The keypoint array is positional. If one annotation lists the points in a different order, every coordinate is attached to the wrong landmark, and nothing visually flags it until training.
Skeleton off-by-one
In COCO, the keypoints array is 0-based but the skeleton pairs are 1-based ids. Tools that mix these draw bones between the wrong joints.
The COCO keypoint format
The de-facto interchange format: 17 person keypoints, a 1-based skeleton, and per-point visibility flags. The full reference (order, skeleton pairs, JSON examples) lives on its own page.
COCO keypoint referenceKeypoint datasets to start from
Public pose and landmark datasets: the standard benchmarks plus downloadable keypoint datasets hosted on DataTorch.
Browse keypoint datasetsThe terms, in one line each#
What is a keypoint?
A keypoint is a single named point on an object, stored as an (x, y) pixel coordinate plus a visibility flag. Unlike a bounding box or a mask it has no area: it records where a landmark is, not how big it is. Keypoint, landmark and joint are used interchangeably depending on the field.
What is a skeleton in keypoint annotation?
The list of keypoint pairs that connect into limbs, such as left_shoulder to left_elbow. The skeleton belongs to the label schema, not to each annotation: every object with that label shares it, which lets a tool draw the pose as you annotate and lets a model learn the structure between points.
How many keypoints does COCO use?
17 for a person: nose, eyes, ears, shoulders, elbows, wrists, hips, knees and ankles. Other datasets use other counts (68 facial landmarks in 300-W, 21 hand points in FreiHAND, 17 animal points in AP-10K). The count is set by the schema, not by the file format.
What do keypoint visibility flags mean?
COCO stores one flag per keypoint: 0 means not labeled, 1 means labeled but occluded, 2 means labeled and visible. Points with flag 0 are ignored in evaluation, while flags 1 and 2 both count, so estimating an occluded point is worth the effort.
A keypoint tool that knows the skeleton.
DataTorch builds the schema into the label: guided point-by-point placement in the declared order, a live skeleton overlay, per-point visibility flags, and COCO import/export. The mistakes above become hard to make.

Tools and community for image annotation: label, review, and share datasets, from everyday photos to the imagery only specialists can read.
© 2026 DataTorch. All rights reserved.